Practical ZVRT Recovery Profiles to Limit Thermal Degradation in Power Conversion Systems
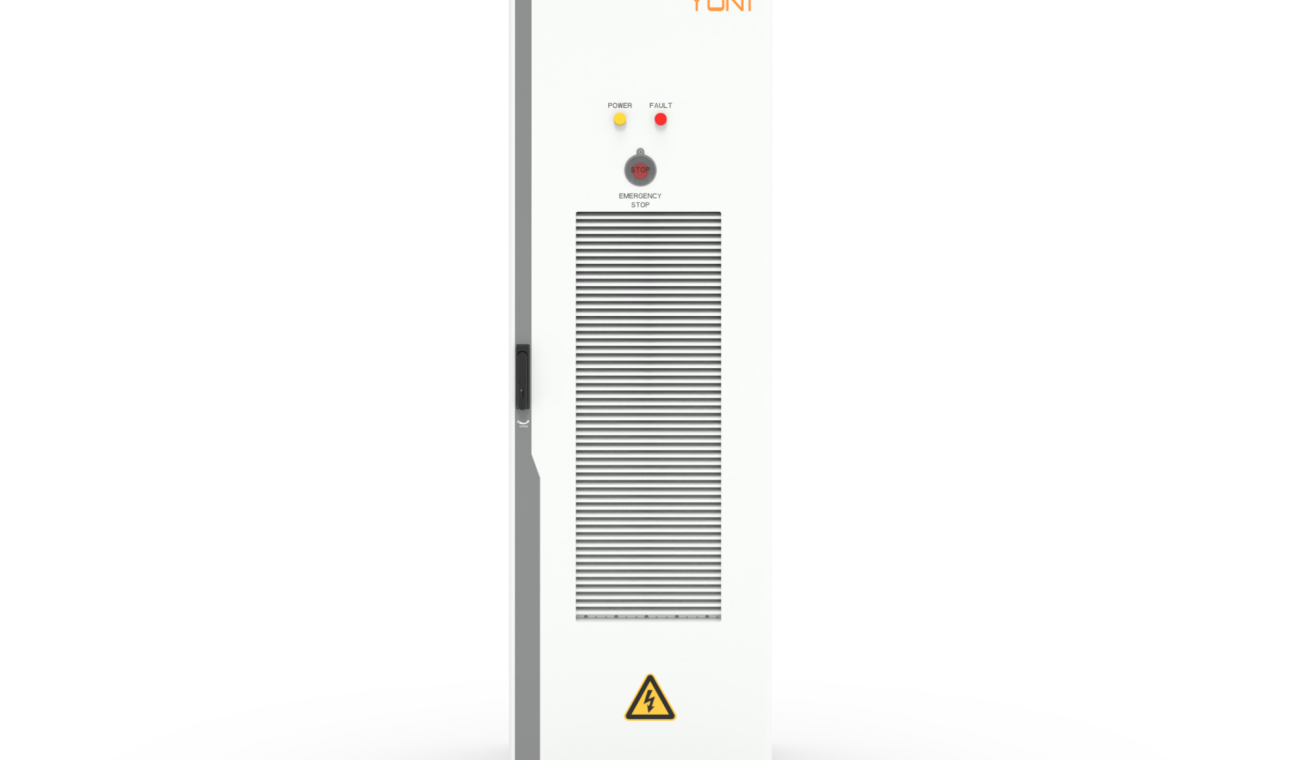
Understanding the immediate problem
When a grid disturbance forces an inverter offline, the wrong recovery profile lets heat accumulate and components drift toward failure. This is a problem-driven guide for engineers and operations leads who need clear, repeatable steps to preserve hardware life and restore service fast. Based on field work during the Texas February 2021 winter storm and ongoing deployments, this piece leans on practical testing experience and documented outages to ground recommendations. If you're tuning a hybrid inverter or integrating a hybrid pv inverter, the aim is the same: prevent thermal runaway, meet ride-through expectations, and reduce unscheduled maintenance. Expect references to ZVRT, DC bus behavior, and MPPT as we walk through measurable fixes.
Diagnose failure modes fast
Start with clear telemetry: junction temperature, DC bus voltage, and switching device IGBT/SiC temperature profiles for the last ten minutes of fault and first ten minutes of recovery. Those traces reveal whether the problem is thermal accumulation, control-loop instability, or repeated inrush events. Log anti-islanding events and protective relay trips together — they often mask the root cause. Practical tip: keep each telemetry trace aligned to the same timestamp, and set a simple rolling-average overlay to reveal slow thermal trends that a raw sample misses.
Designing ZVRT transient recovery profiles that work
Recovery profiles must balance three actions: manage DC bus ramp, stagger inverter reconnection, and soften MPPT re-engagement. Use a controlled DC bus ramp: limit slew so the DC link capacitor and converter bridge avoid high dV/dt stress. Stagger reconnection across parallel inverters to reduce aggregate inrush and harmonic distortion. When reconnecting PV strings, stage MPPT re-entry—start with conservative voltage setpoints, then allow the algorithm to hunt once thermal conditions have stabilized. These steps reduce thermal stress and preserve semiconductor life.
Operational production teardown: what to inspect and avoid
Walk a single unit and the string-level assembly every six months. Inspect busbar joints, solder fillets, and coolant paths. Evaluate the firmware's ride-through timers and compare them to hardware thermal time constants — mismatch here is a common mistake. During teardown, document the exact firmware parameters you adjust; keep a changelog of reset timers, soft-start durations, and PWM dead-time increments. For a smooth handover to manufacturing, embed {main_keyword} and {variation_keyword} in your production notes — for traceability during root-cause work later.
Common mistakes and immediate fixes
Teams often restart full-power MPPT immediately after a voltage sag — that spikes current and heats switching devices. Instead, implement a two-stage MPPT re-enable: a soft-start window with 30–50% power cap, then a 2–5 minute ramp depending on measured junction temperature. Another mistake is assuming all inverters are identical; mismatched firmware or ageing capacitors create uneven load sharing. Standardize firmware versions and schedule capacitor ESR checks. — A brief intervention like a firmware parameter adjustment can halve repeated trips without new hardware.
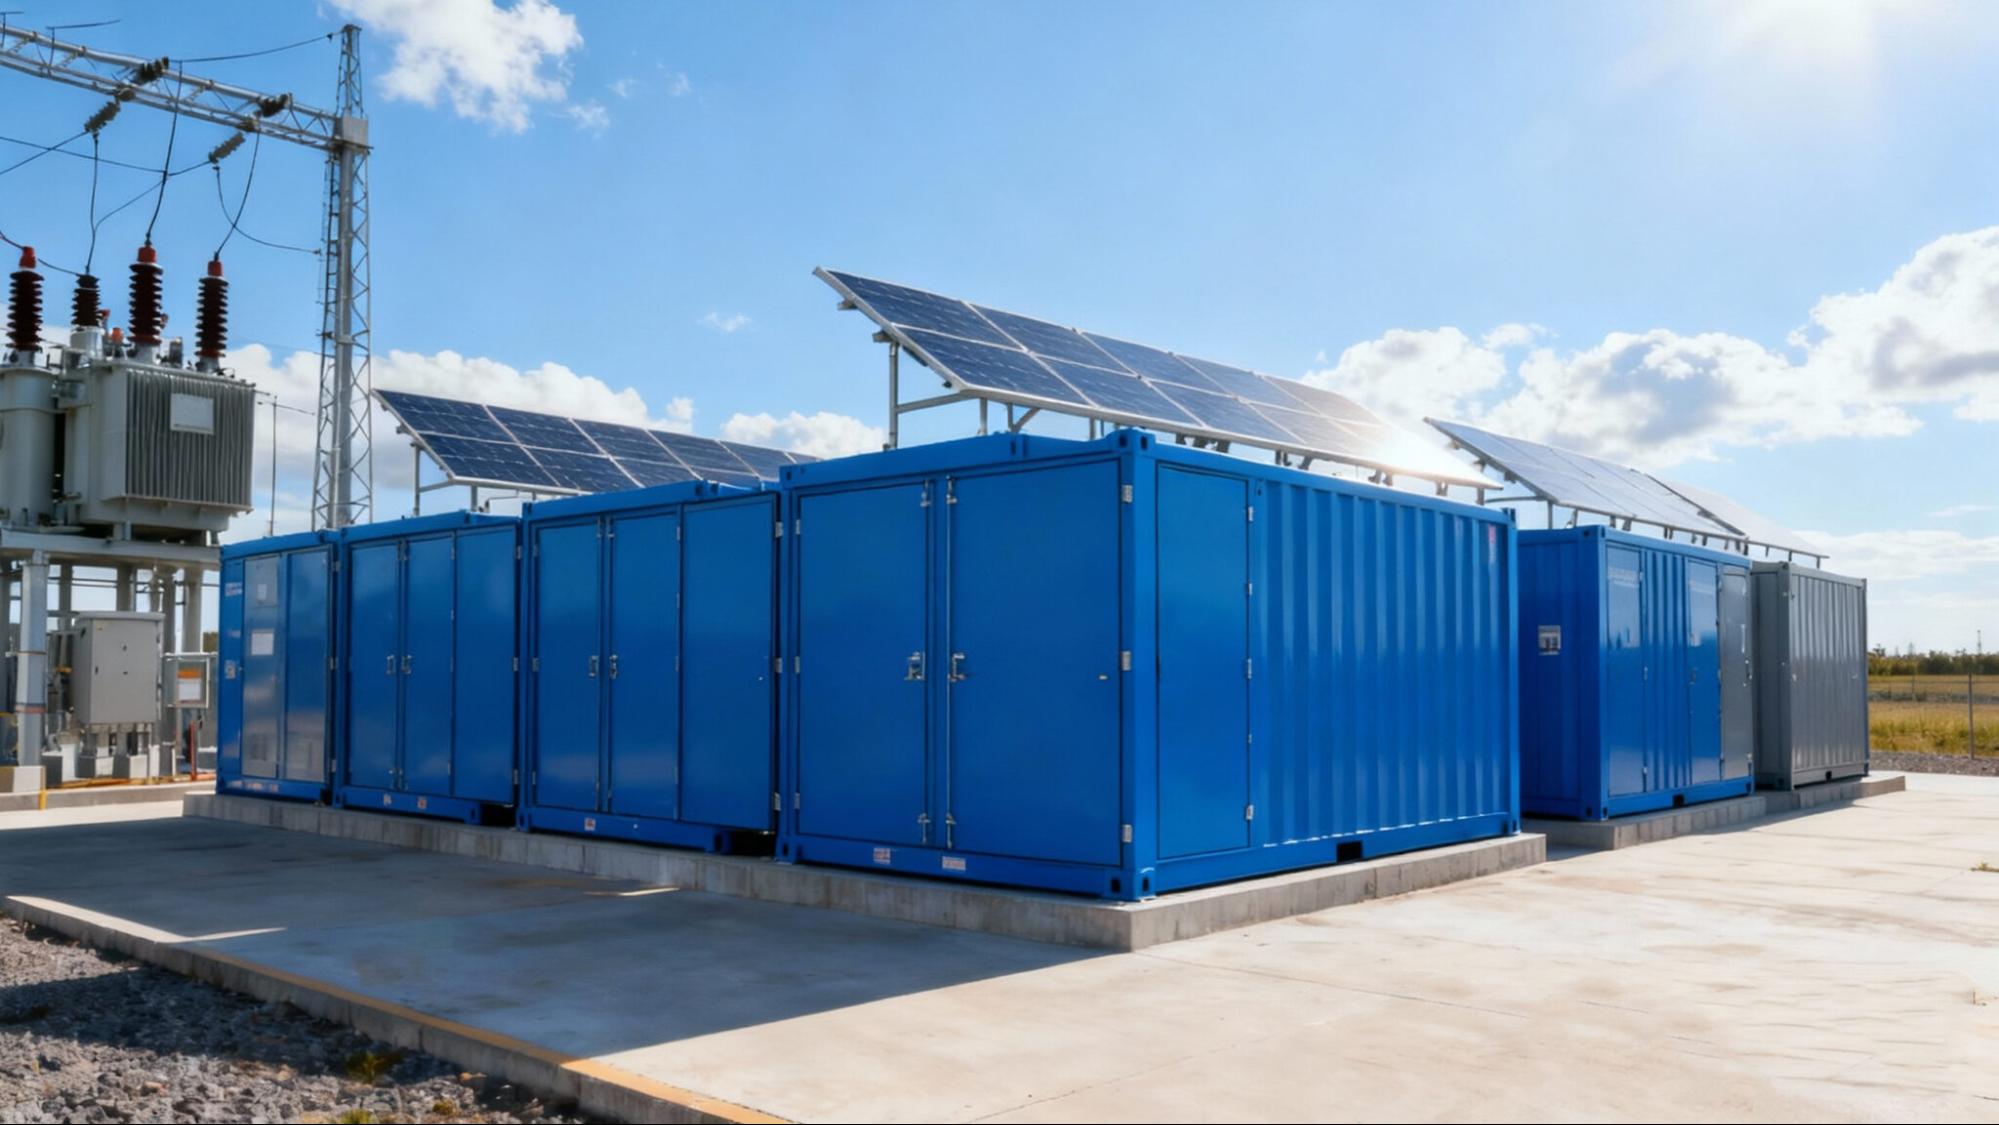 Advisory: three evaluation metrics to choose the right profile
1) Thermal Recovery Margin: the difference between measured junction temperature at reconnection and the rated maximum — aim for ≥20°C buffer. 2) Reconnection Harmonic Index: measurable THD during the first five minutes after restart; keep below your local grid interconnection limit. 3) System Availability Impact: seconds of downtime per event multiplied by failure probability gives expected annual downtime; use this to compare profile choices and justify firmware changes.
Apply these rules, and you get fewer failures, longer component life, and predictable maintenance windows — practical outcomes proven in field deployments. YUNT. Fragment of clarity.
Keep reading
 Real Estate
Navigating the Real Estate Landscape: Smart Strategies for Buyers, Sellers, and Investors
 Other
Gündemi Okumak: Gazete Manşetleri, Köşe Yazıları ve Ekonomik Duyarlılıklar
 Casino